Project № 13
Geonosis-AI
The Robot Deployment Agentic Factory. Get from any embodiment to perform any task with a fleet of long running agents. Built solo at Cal Hacks 13.0, Honorable Mention in the SpacetimeDB track
Built for CalHacks 13.0 solo, and won Honorable Mention in the SpacetimeDB track out of 150+ projects.
I built Geonosis because I see first hand how difficult deploying a robot is at Northstar Robotics.
For any frontier model such as π0.5, and even world models, robots require clean demonstrations in order to perform any task with at least some reliability.
However getting data either requires VC money to pay 600k+ for data, or you set up your own data collection infrastructure. Then you still need to figure out how to train your models, and it's not as simple as just throwing data at π0.5. What data to collect, and how you collect it, is vitally important. This creates a huge barrier to entry for most people deploying robots.
I built Geonosis AI to be the robot deployment factory. From any embodiment and task, you get a fleet of agents that run the entire deployment pipeline: collecting data by outsourcing operators, running evals on a physical robot, training, and shipping the checkpoint.
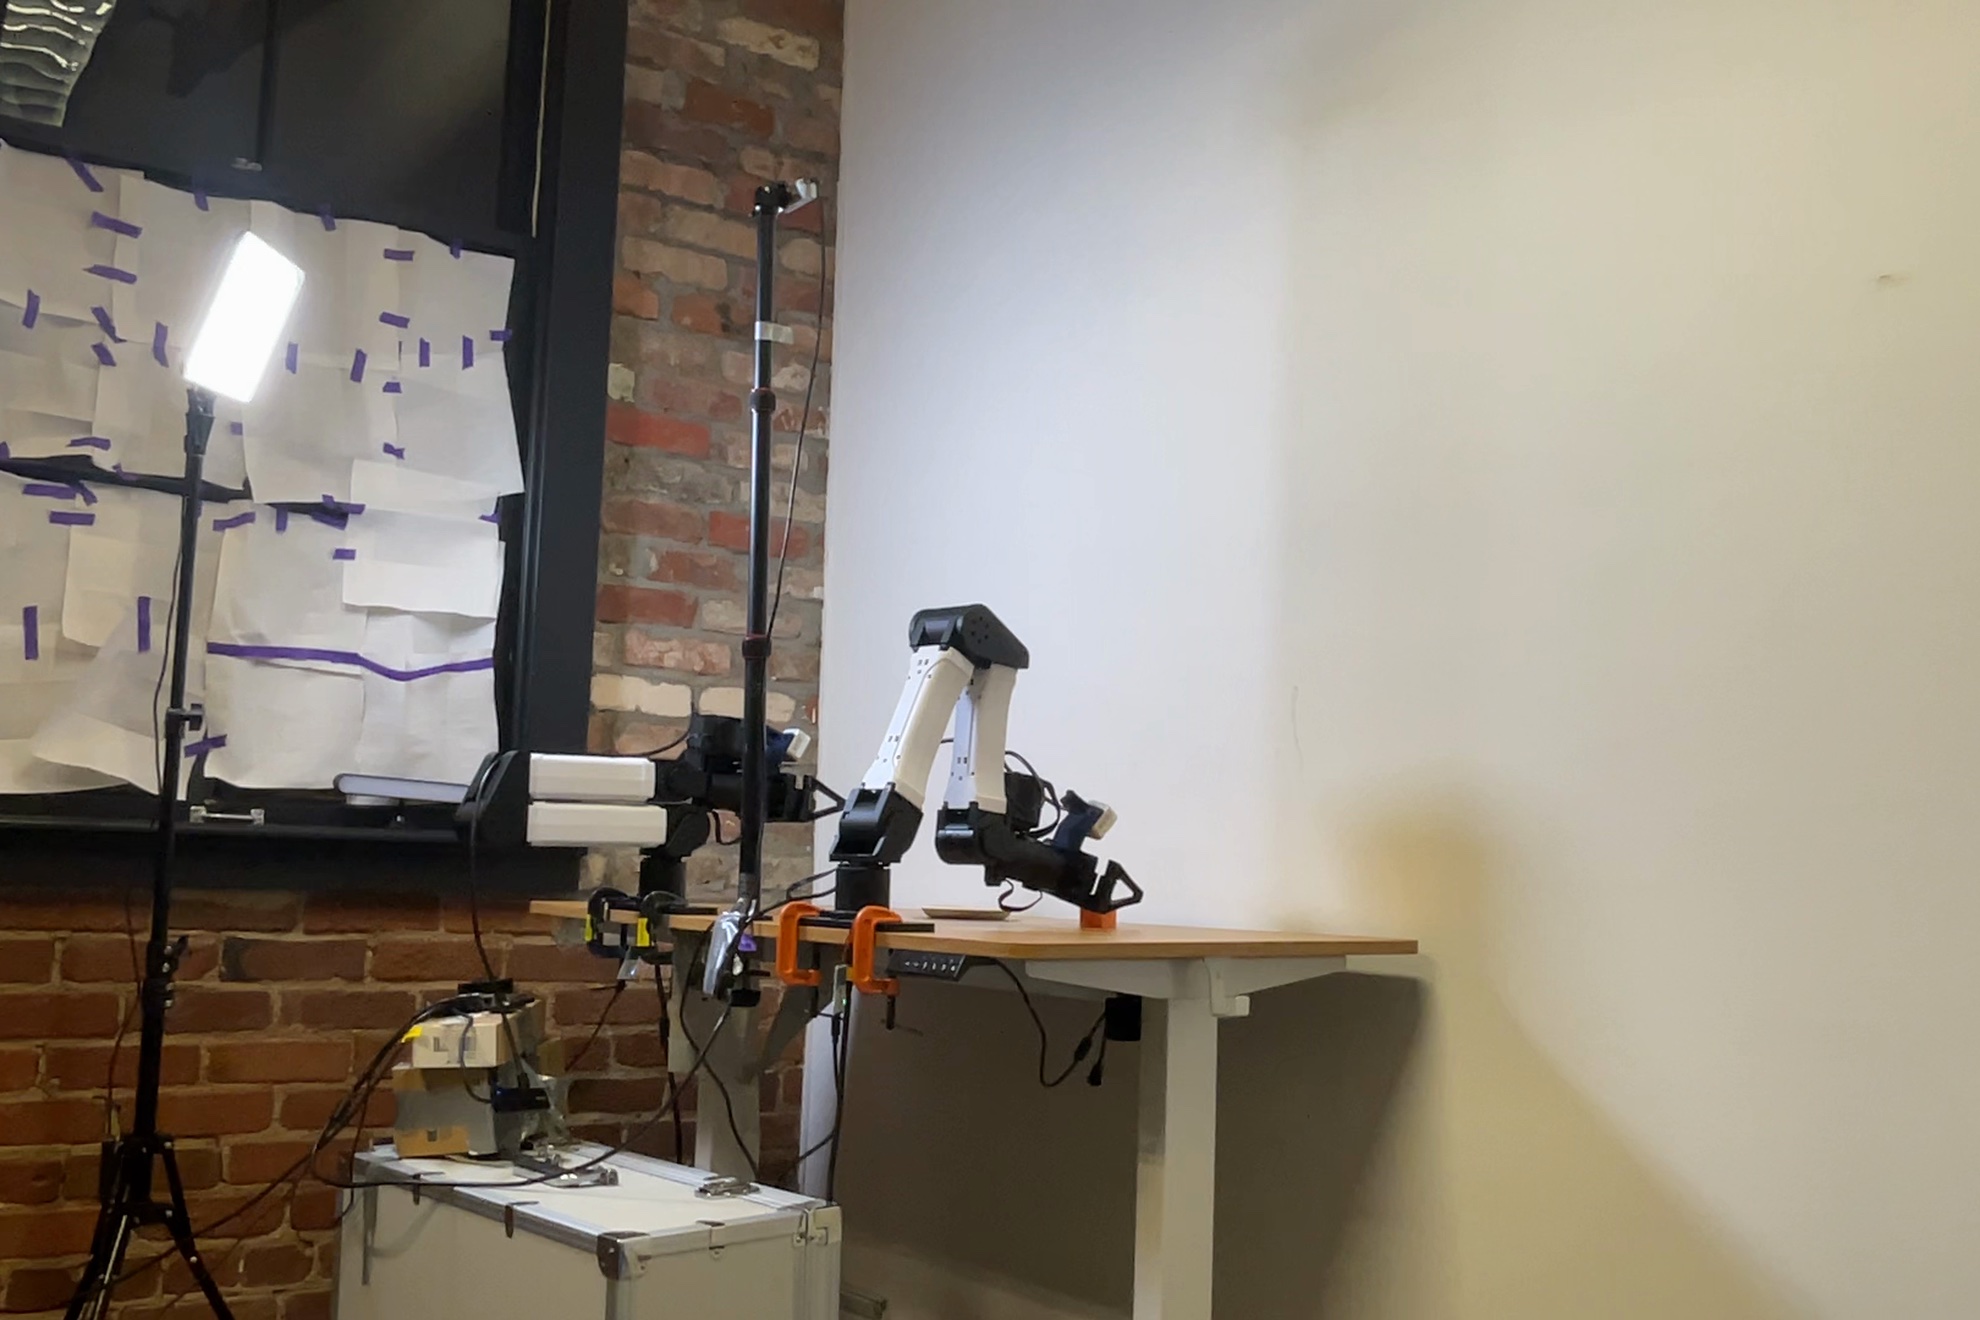
How it works
You file a ticket: "Pick up the cube and place it on the plate, 75% reliable, $50 budget." The ticket then moves down a line of agent stations, like a part moving through a factory.
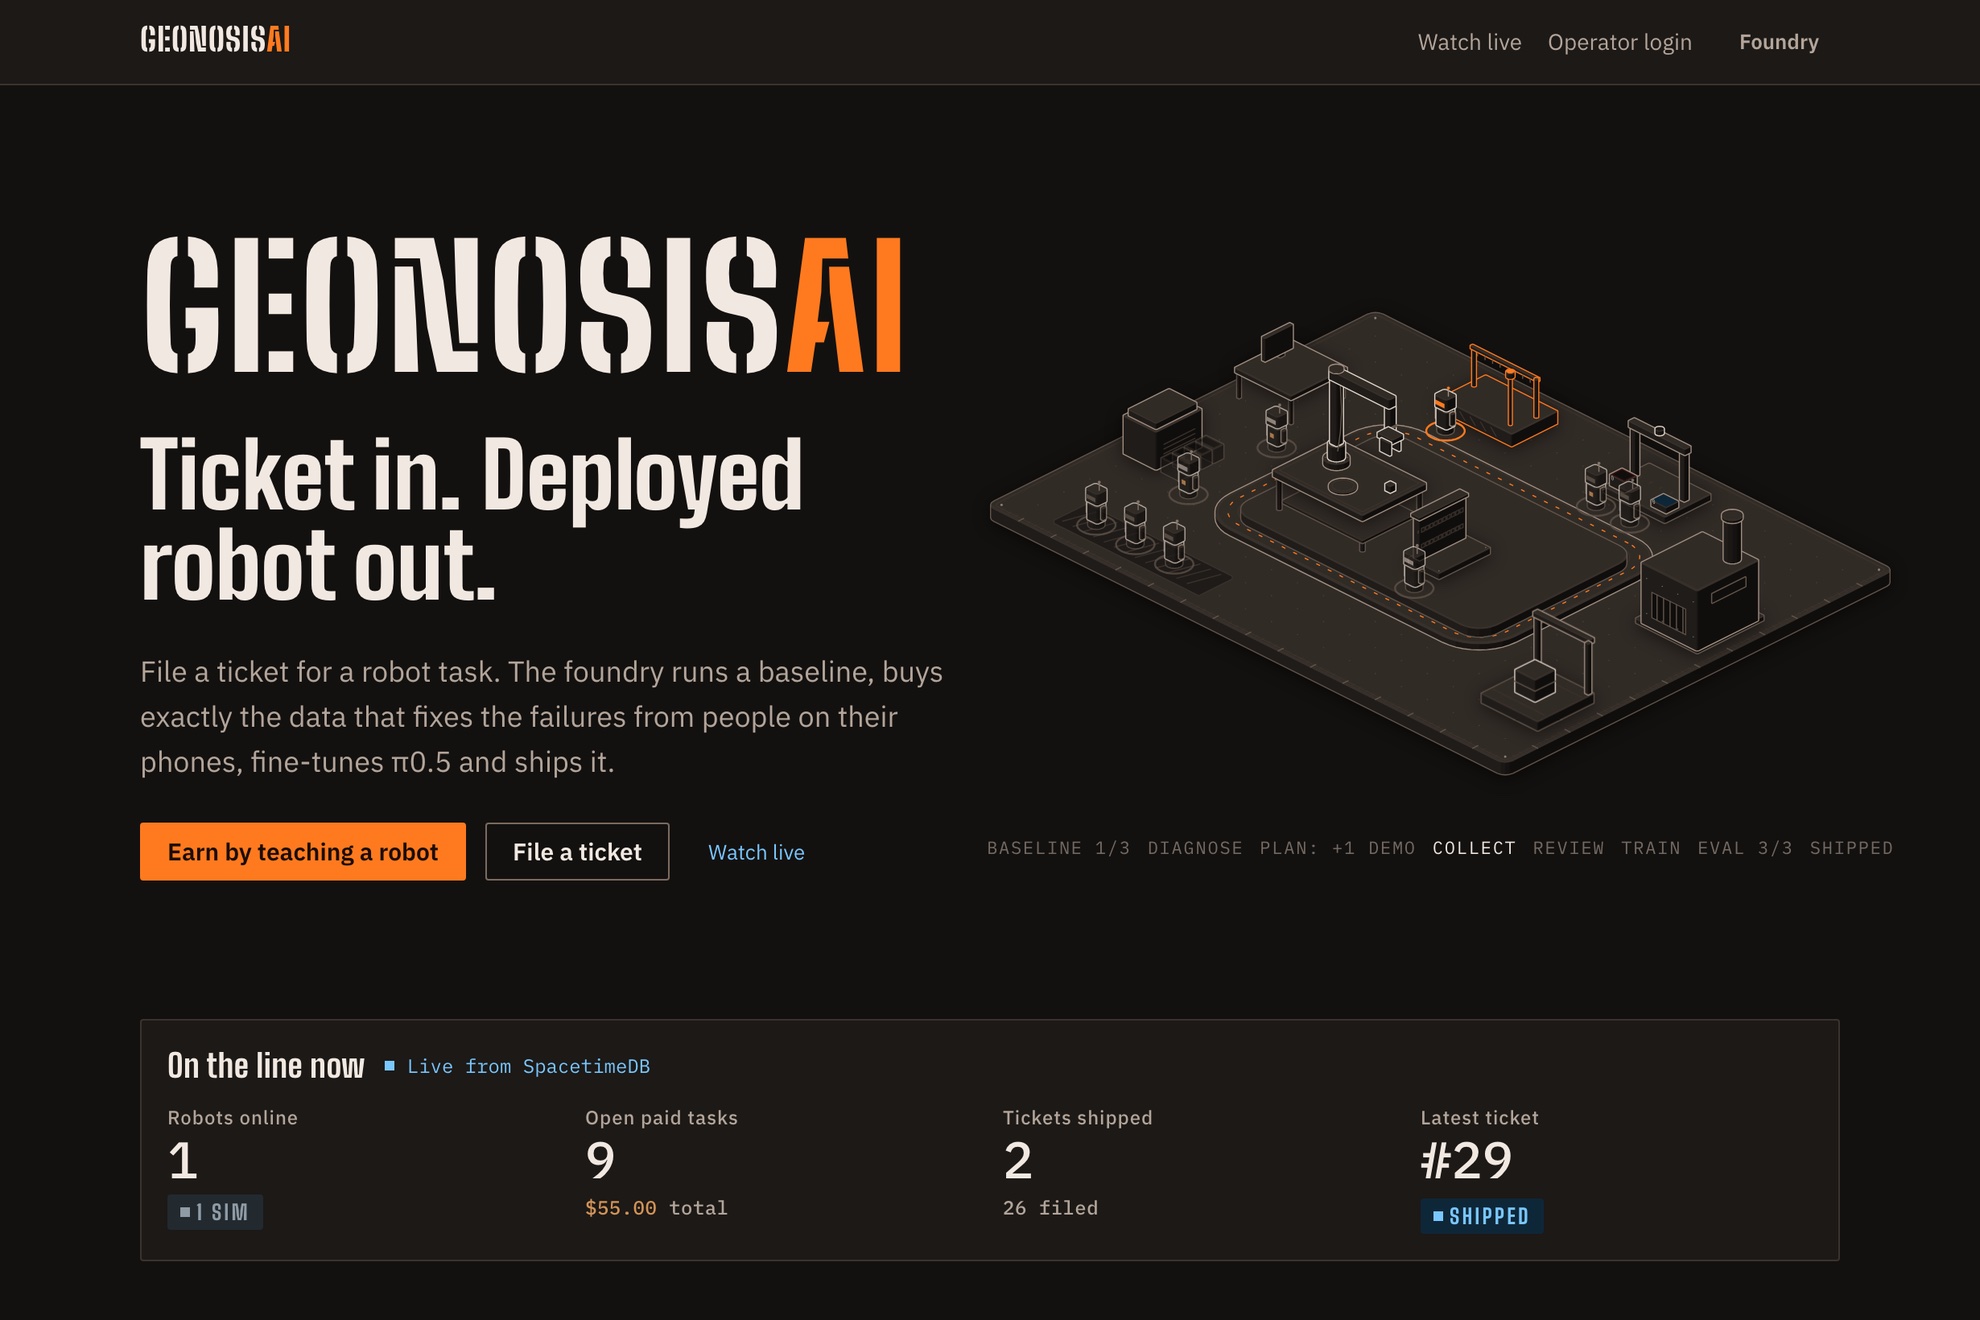
- Baseline. The robot runs the task on its current policy. Every trial is recorded with its outcome.
- Diagnose. Claude groups the failed trials by why they failed, from trial notes, timings and camera frames.
- Plan data. The planner reads the failure clusters, the success rate and the budget, and decides what data fixes them: recovery takeovers (the robot pauses mid-failure and a person takes over) or clean demos, and how many. Its reasoning has to quote a failure cluster, and a human approves the spend.
- Collect. Paid tasks go out as job drops on Discord and as texts ("Reply YES to claim"). A contributor claims the task on their phone, sees the robot's cameras, drives the arm from the browser and hands control back. In the demo the robot sat behind a Cloudflare tunnel, so anyone who got the text could tunnel in and give a demonstration.
- Review. Deterministic checks (timestamps, jerk, dropped frames, length) plus a Claude vision review. Rejected episodes show why. Accepted ones get paid (Stripe test mode).
- Train. A π0.5 LoRA fine-tune on an H100 on Modal, from the accepted episodes converted to LeRobot format.
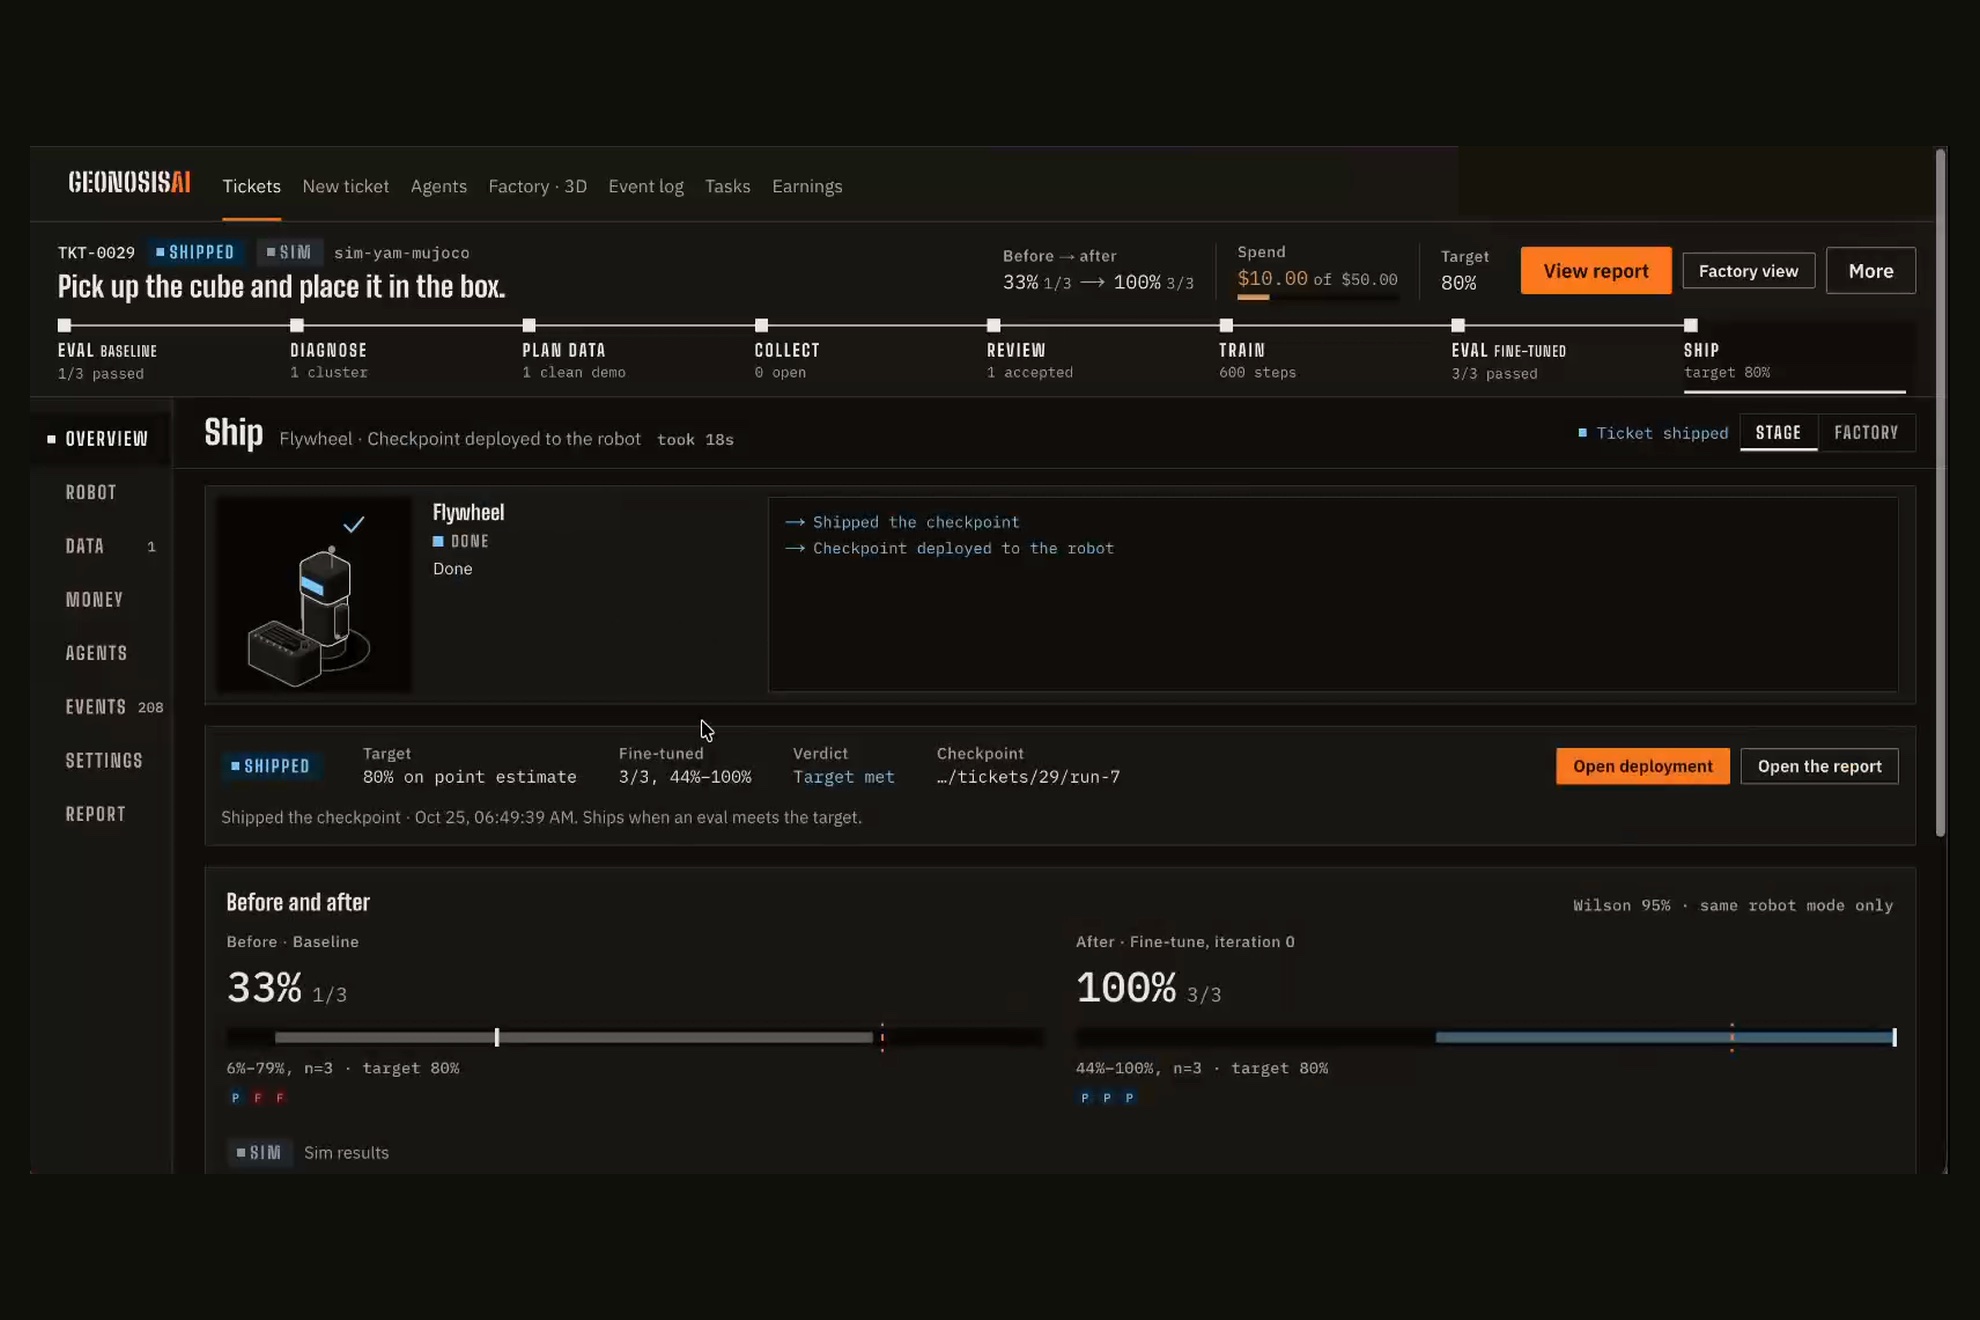
- Eval and ship. The new checkpoint runs the same eval. If it clears the target it ships with a report. If not, the line loops back and buys more data.
The eval agent is also what decides what data is needed. If the robot is failing in a specific way, it probably needs recovery data for that failure, not more generic clean demos.
Here is the line running on the real arm:
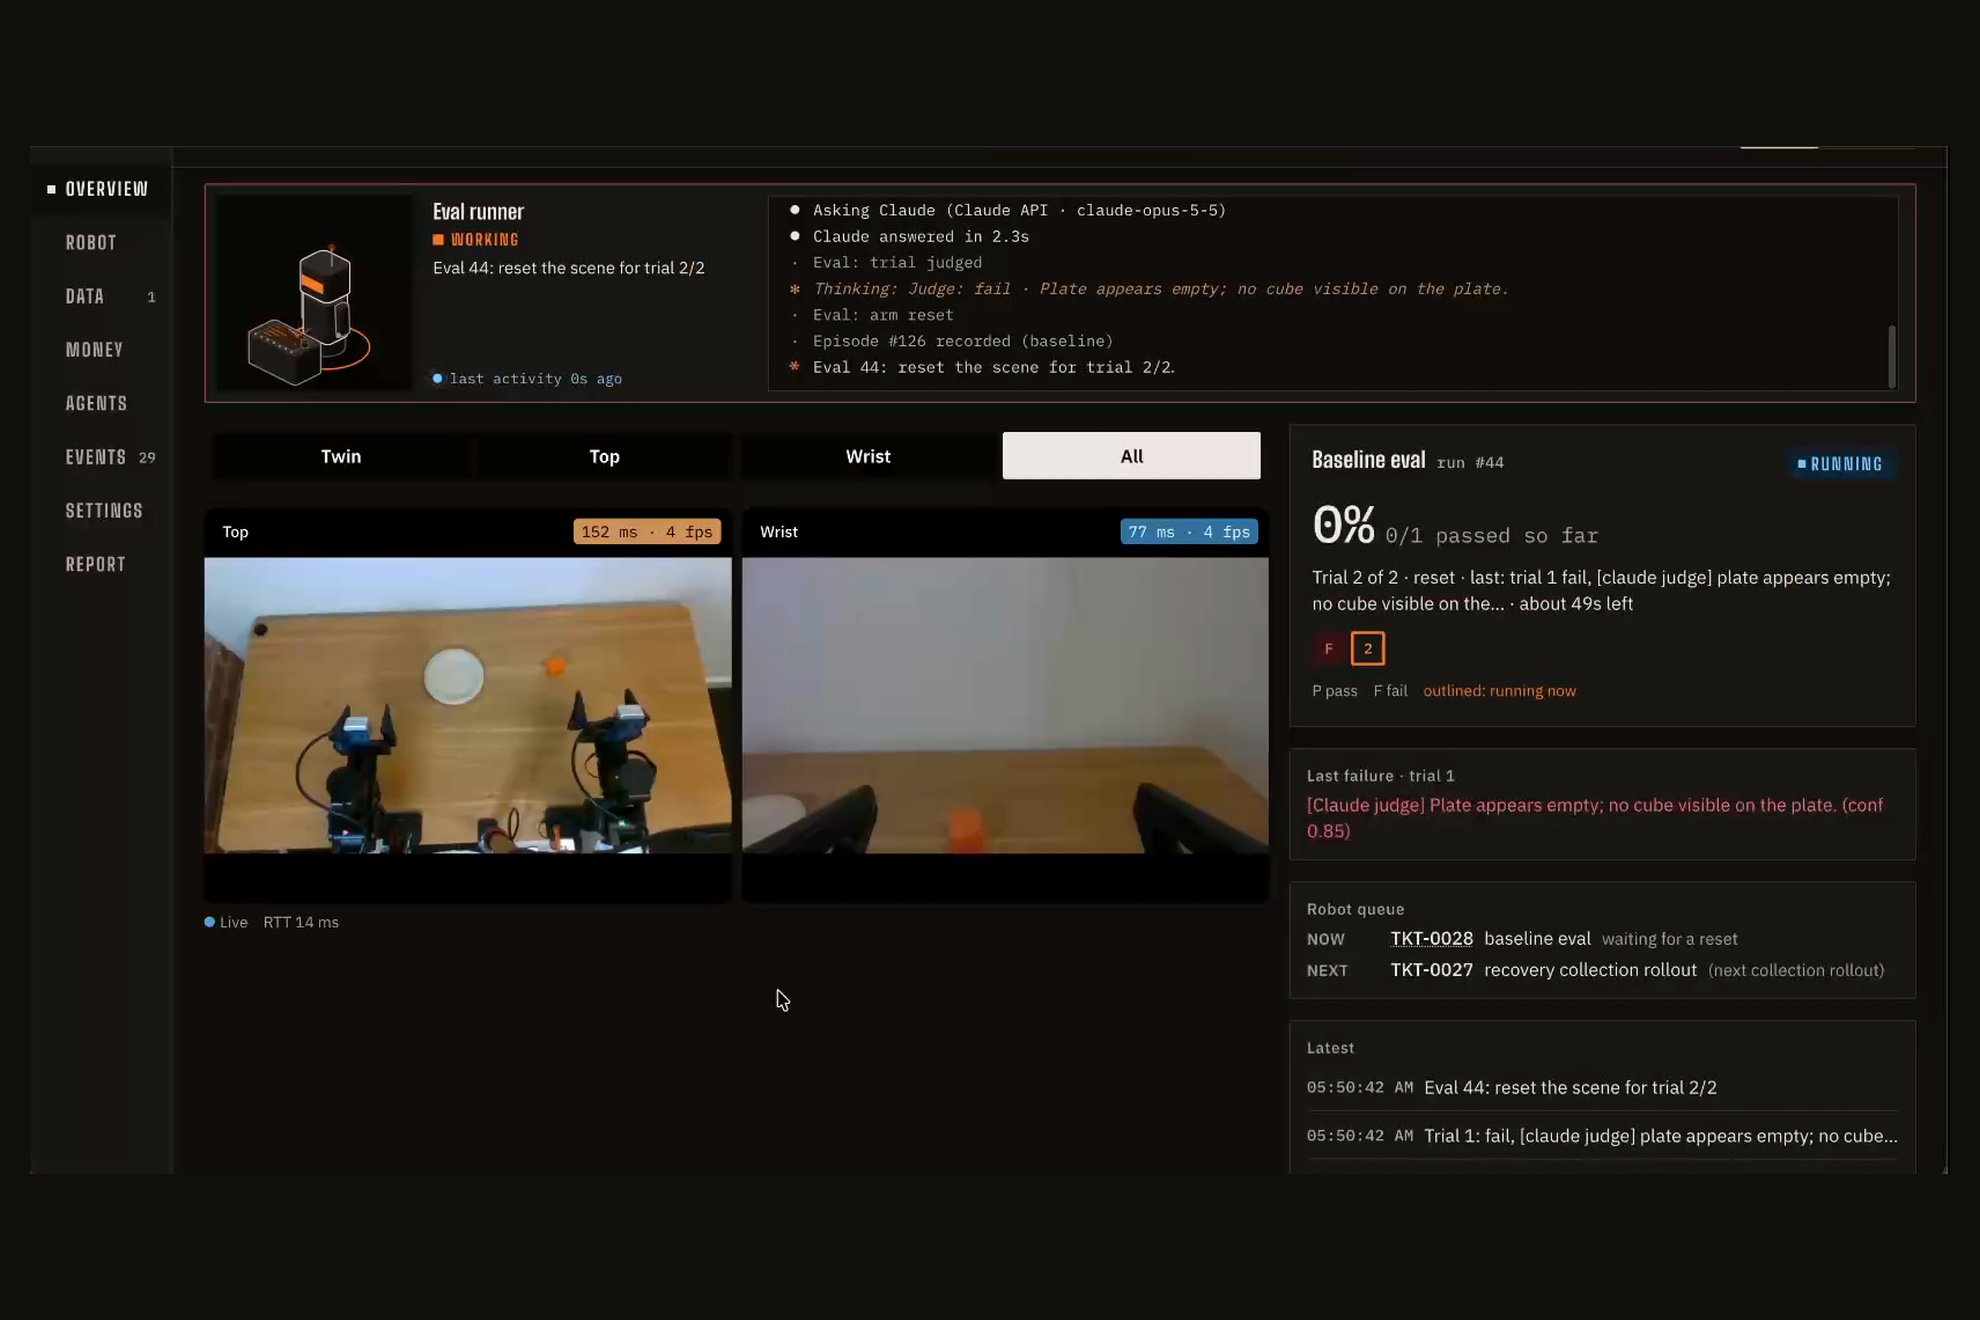
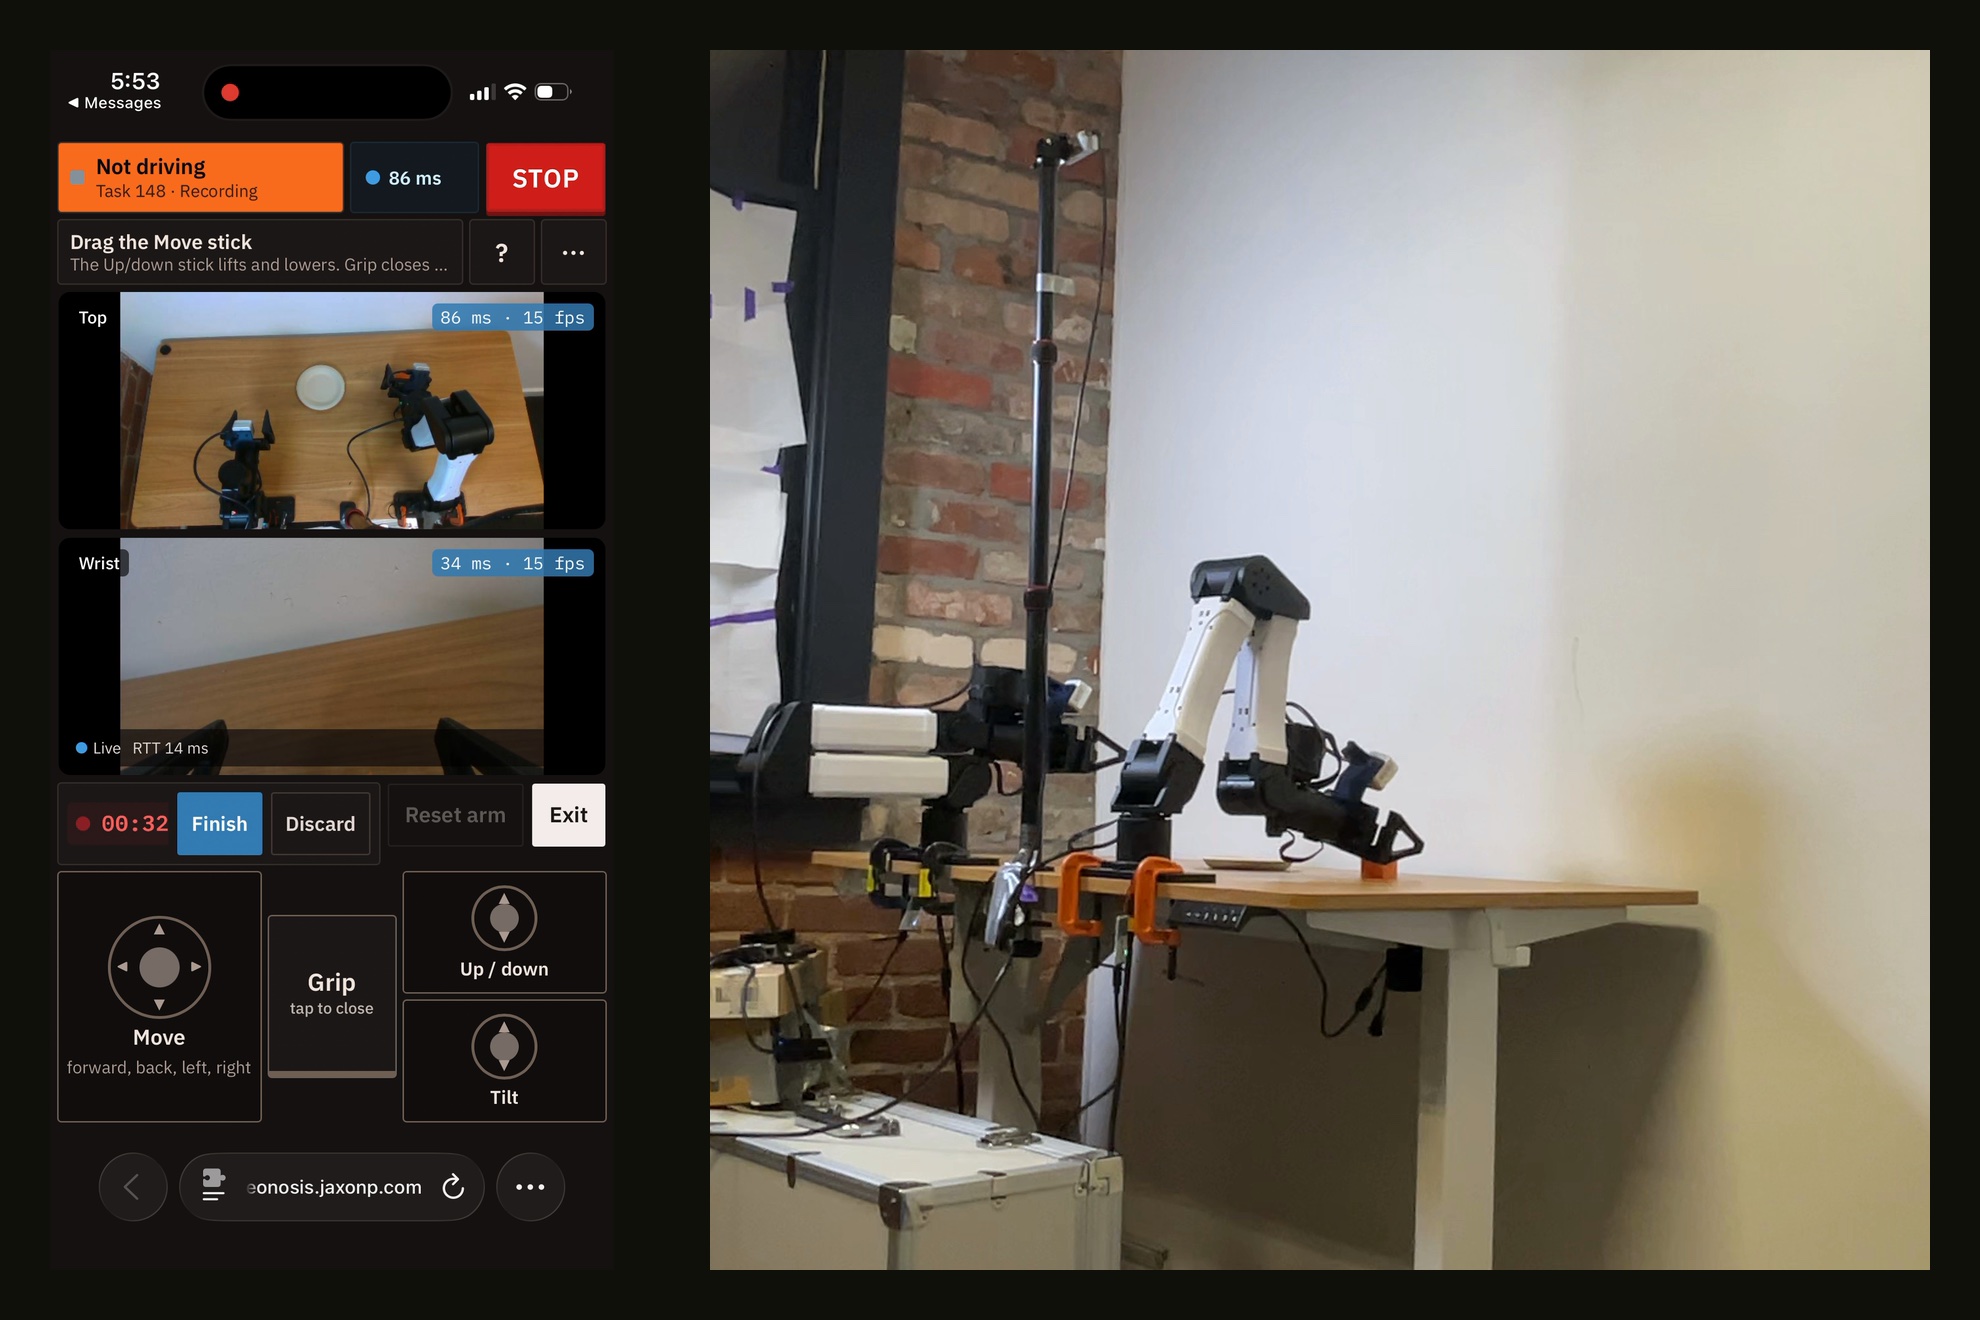
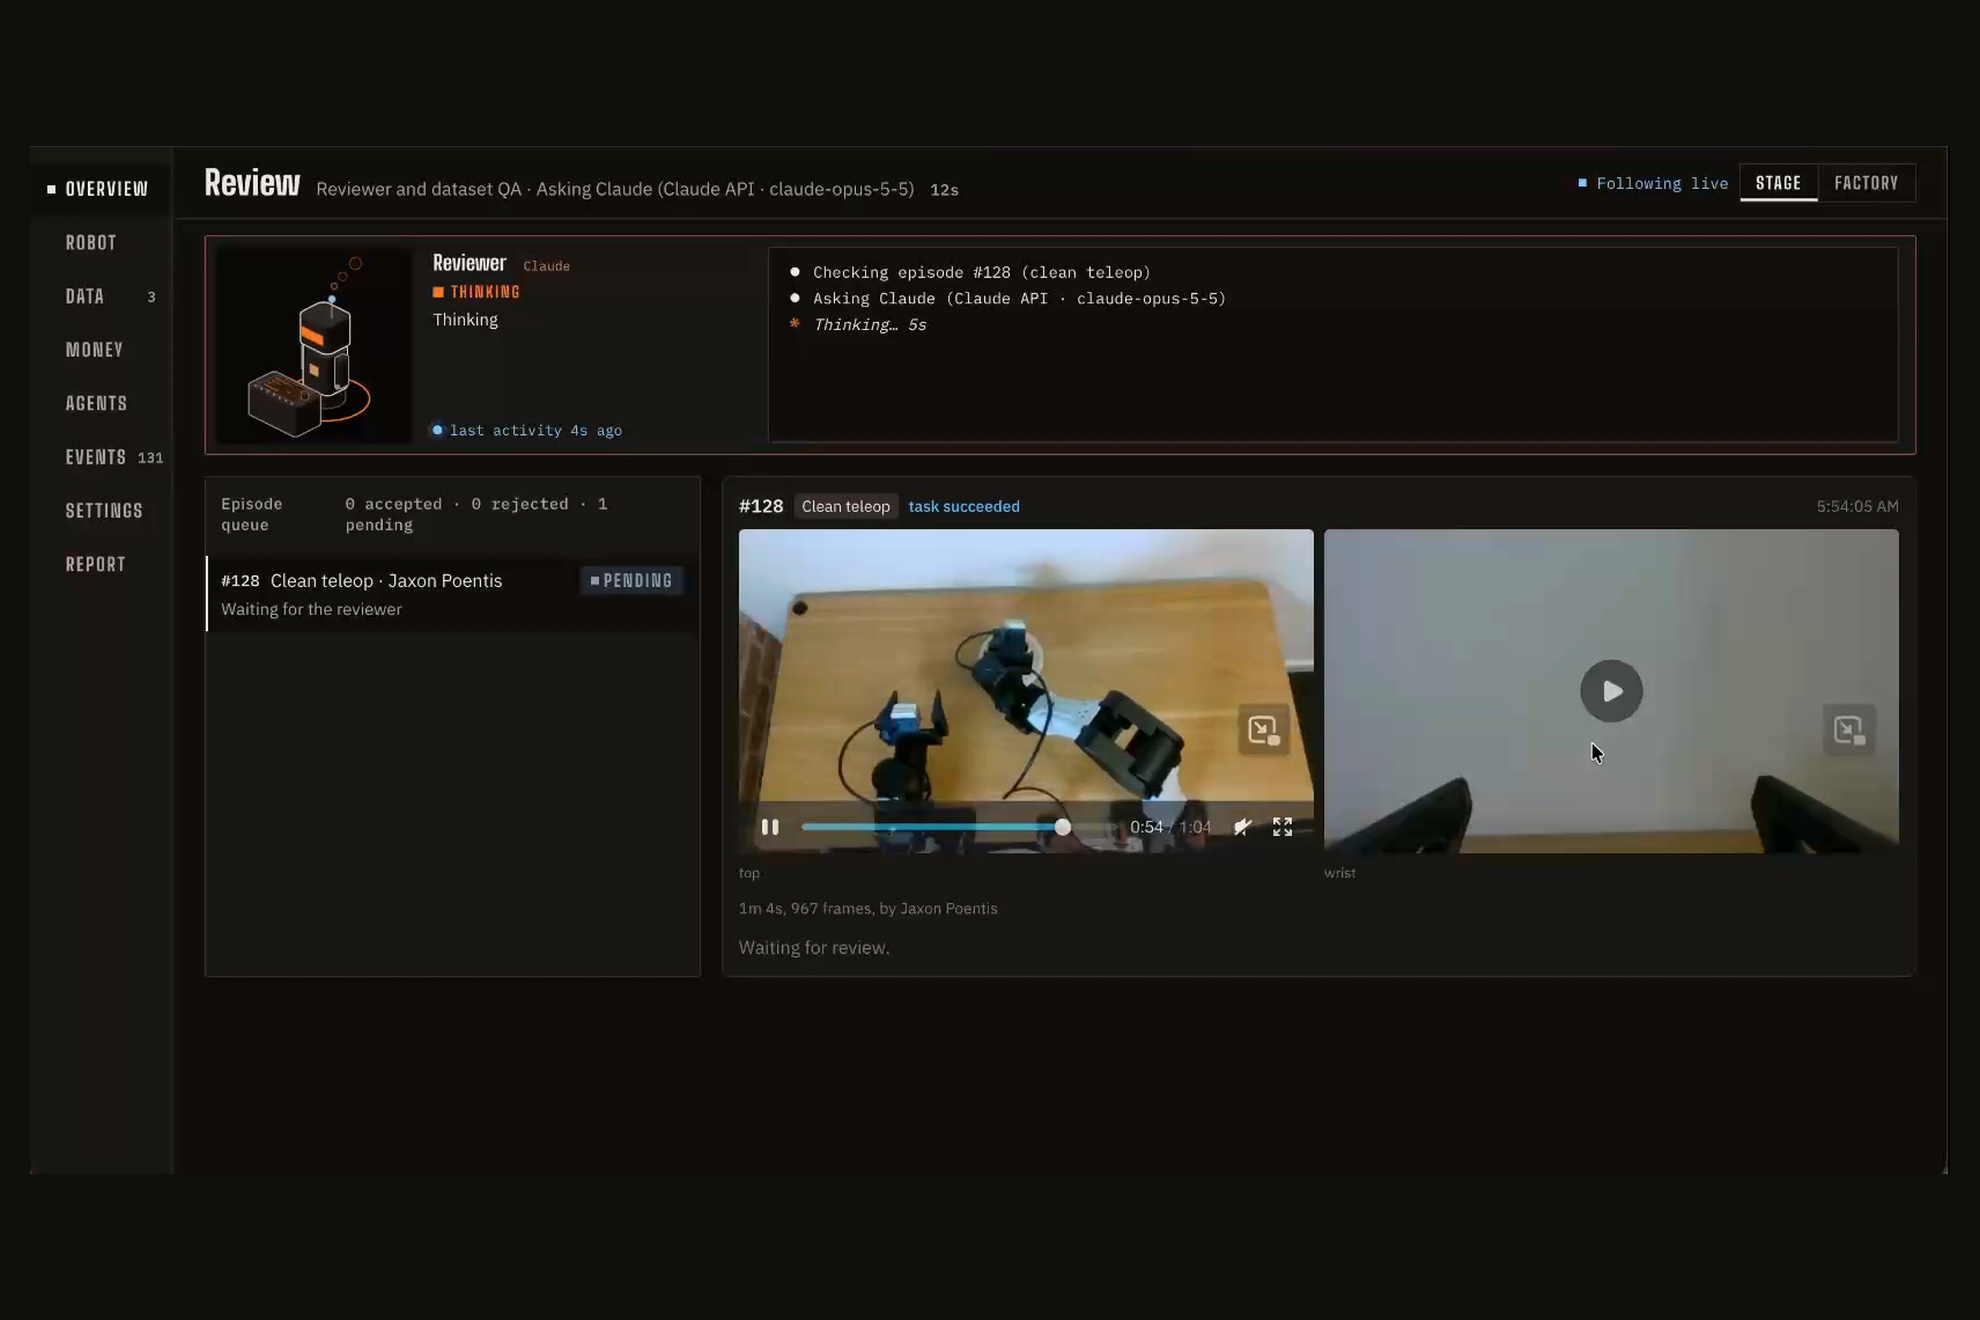
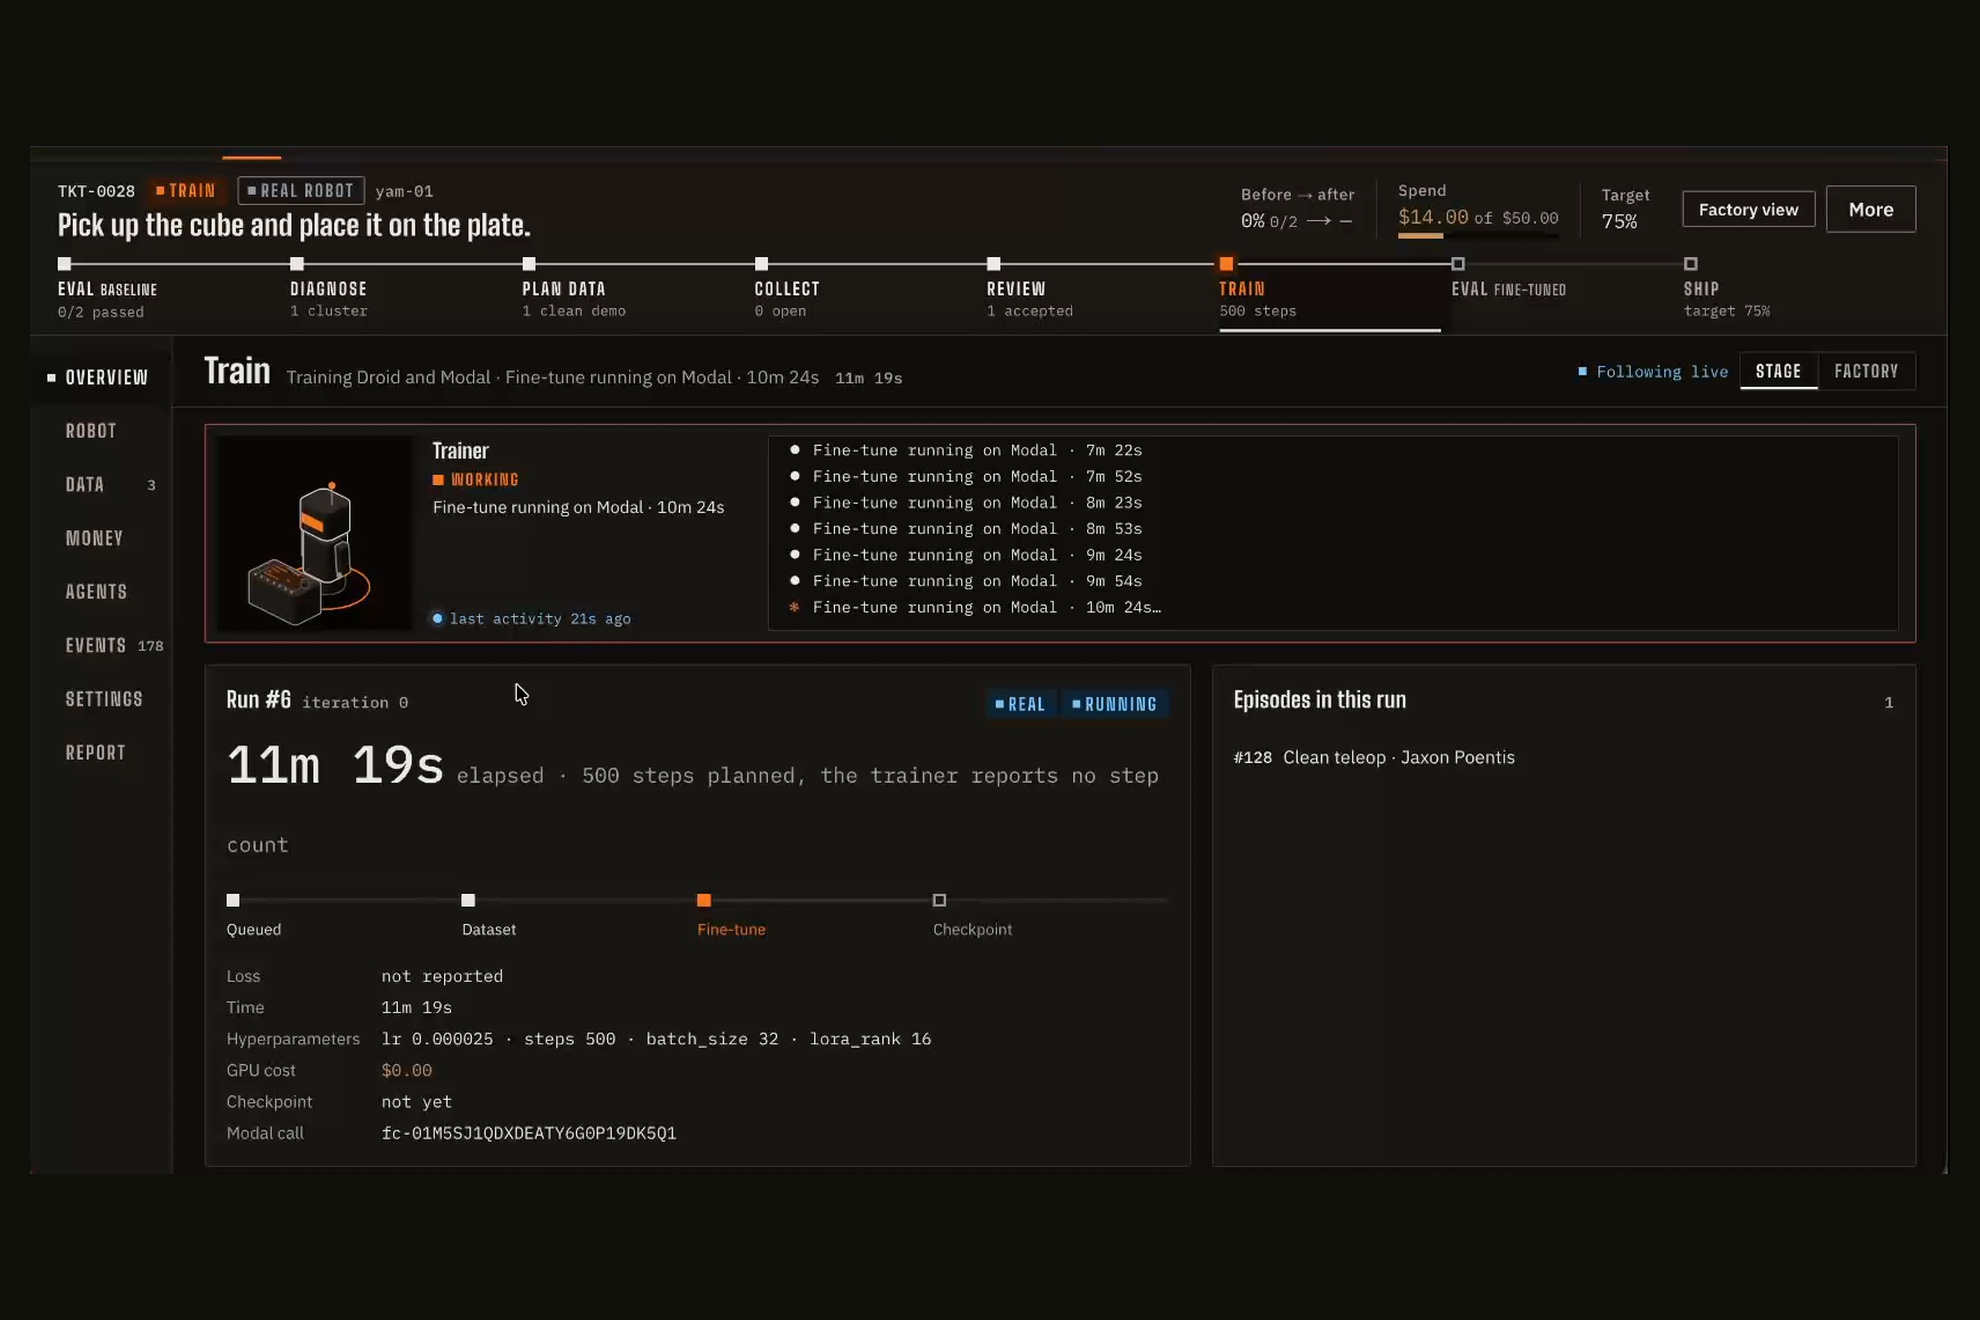
Success rates always show a Wilson 95% interval, because with around ten trials the point estimate alone lies. At 10/10 the lower bound is only 0.72.
Agents that sleep on the database
Under the hood we use Factory Droids plus the Claude API to make a swarm of agents, each with its own role. SpacetimeDB is the real-time database that decides when each of them gets kicked off.
Every service, agent, robot and phone reads and writes the same SpacetimeDB tables. The orchestrator, three kinds of Factory Droids, the Jetson, the MuJoCo sim, the web app and every contributor's phone all share 23 tables, and the only way to change them is through about 55 reducers. The safety rules live inside those reducers, not in prompts:
- one arm-control lease per robot, so two phones can never drive the same arm,
- no payout can exceed the human-approved budget,
- a droid can only point training at a dataset where every episode was accepted by review,
- the event log can only be appended to, never edited, and carries a chain hash.
The part I like most is how the agents wait. A droid ends its turn with one line:
WAITING_FOR dataset:accepted_count>=5
and goes idle for free. No process is held open. A resume bridge in the orchestrator re-checks that predicate on every row change, and when it turns true it wakes the same Factory session with what changed. In testing, an accepted review woke a parked Data Droid in 597 ms.
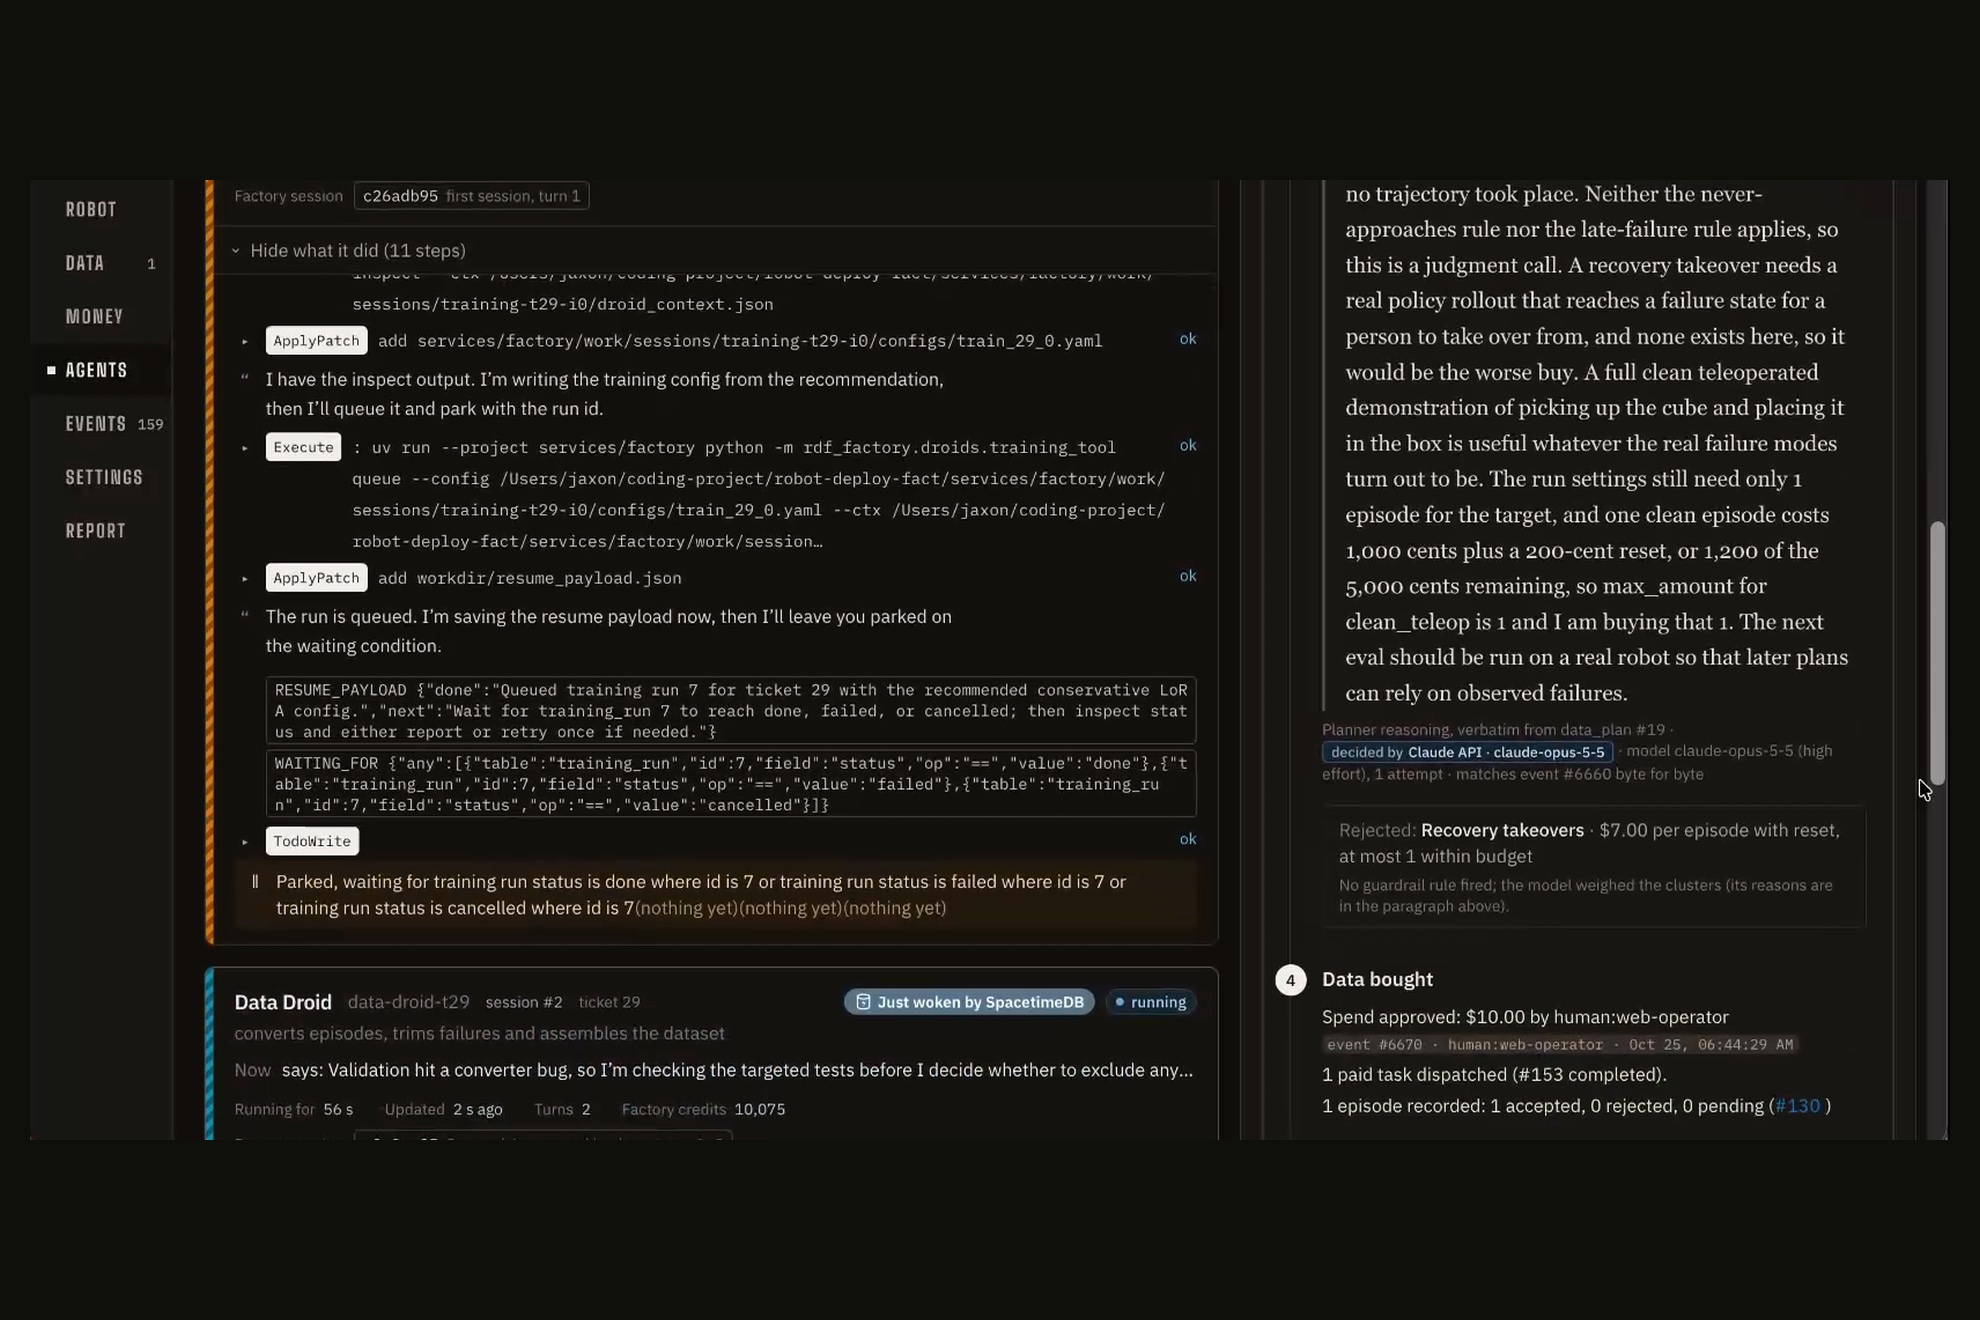
Three droids do the work a robotics engineer would otherwise do between steps. The Onboarding Droid sets up a new robot's adapter and safety checks. The Data Droid validates the accepted episodes, cuts the failure frames before each takeover and assembles the LeRobot dataset. The Training Droid sanity-checks the data before any GPU is spent, picks hyperparameters, queues the H100 run and sleeps. If the run hits an OOM, it wakes, halves the batch and retries once.
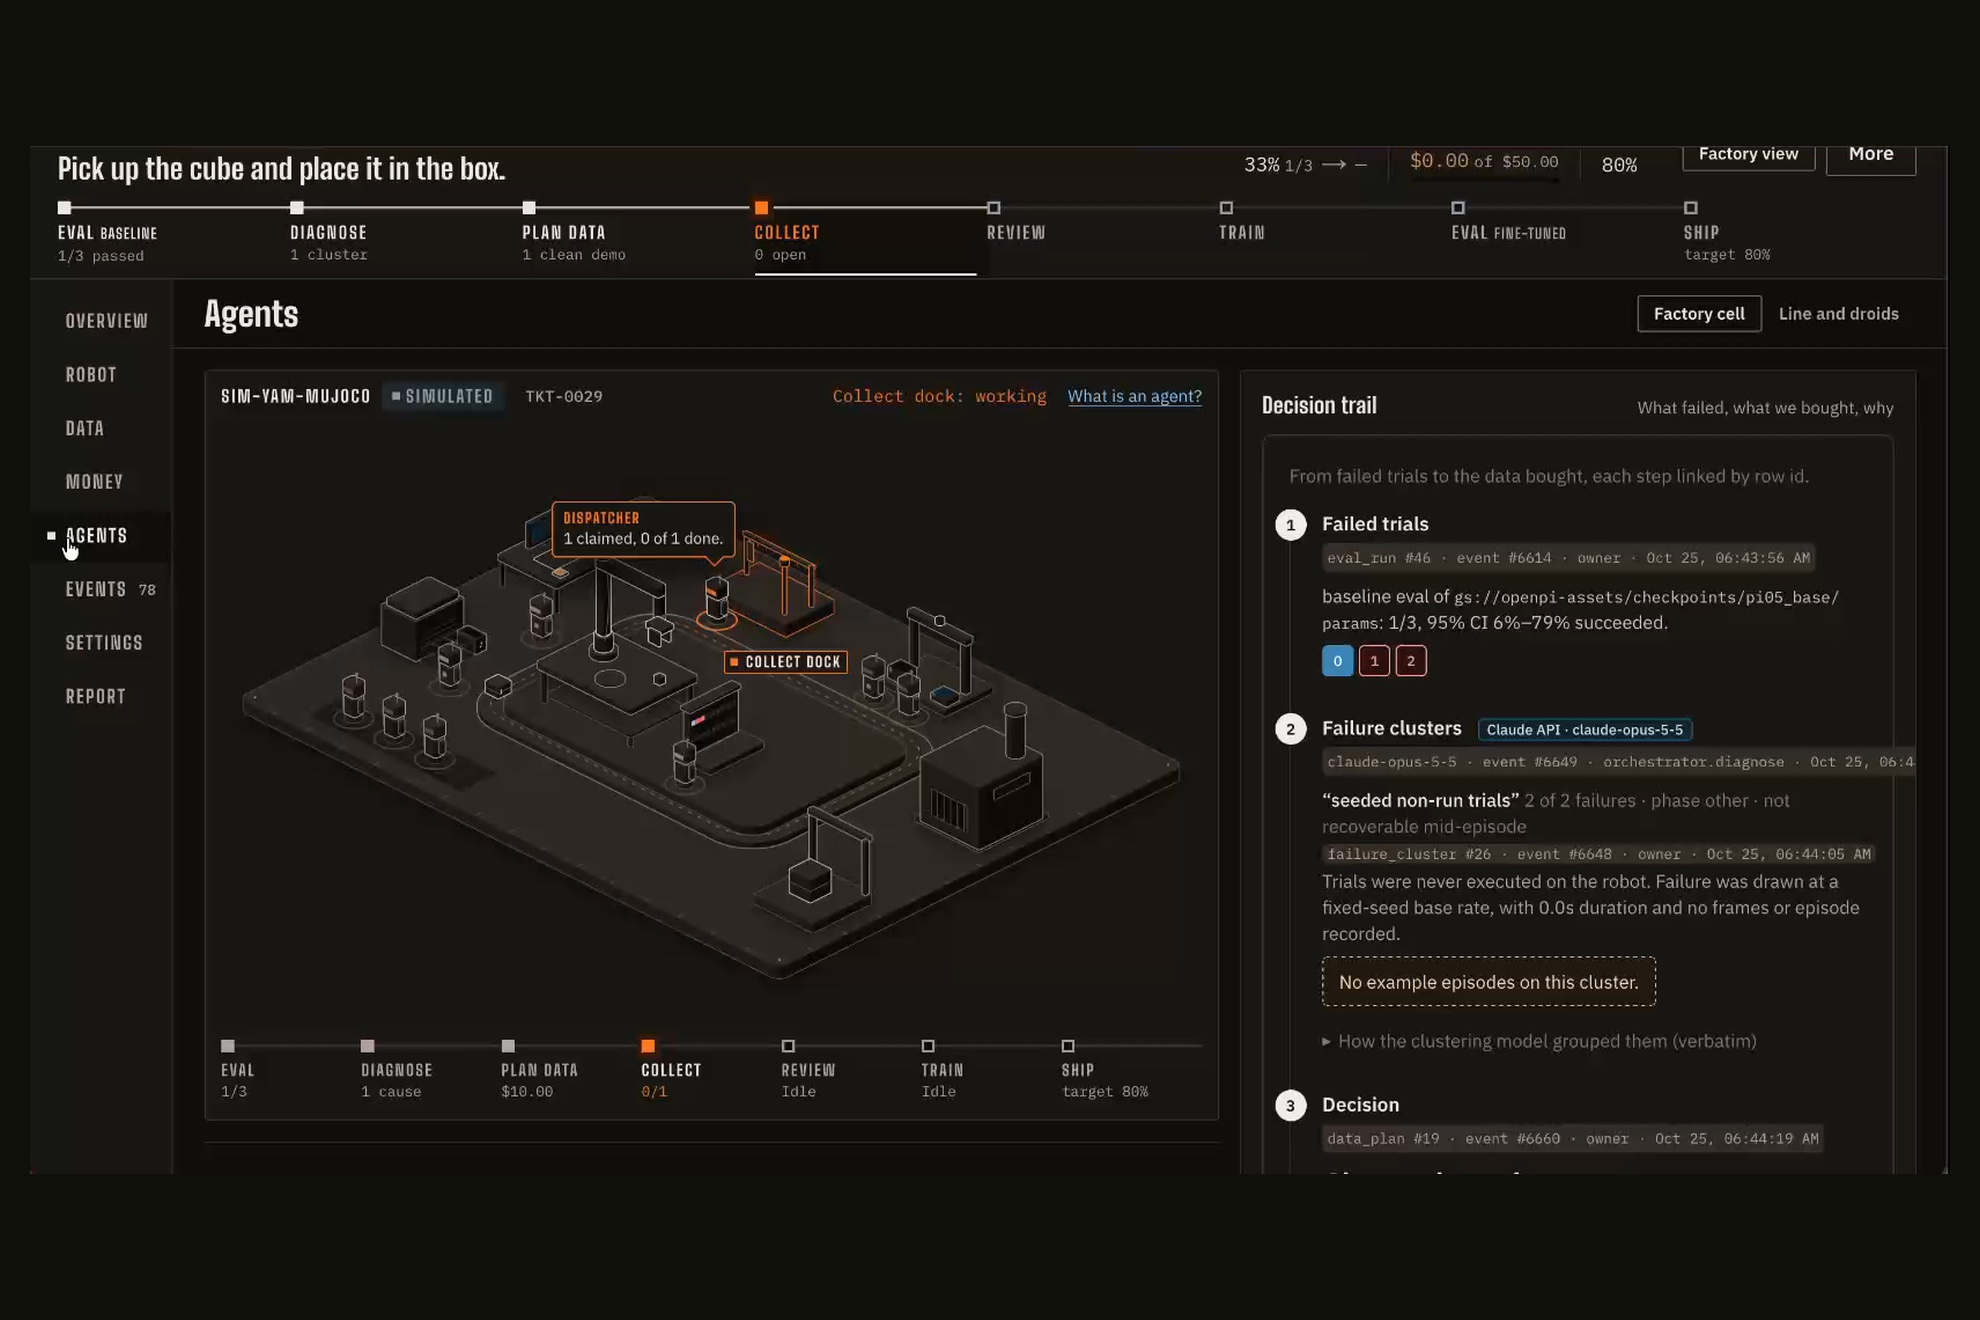
Everything a droid does lands as an event, so the factory floor shows droids riding to their station, sleeping with their predicate on screen, and waking when the database wakes them.
The robot side
The robot client runs on an NVIDIA Jetson next to the real I2RT YAM, and the same code runs a MuJoCo model of the same arm. One adapter interface, one safety layer in front of every command: joint limits, velocity and acceleration caps, a workspace box, a watchdog and a soft e-stop. Sim and real numbers are never pooled.
Inference is remote. The policy server on Modal hot-swaps checkpoints, and the round trip is about 157 ms, which is several control steps. The robot runs 50-step action chunks asynchronously and crossfades between them to hide it.
What actually ran
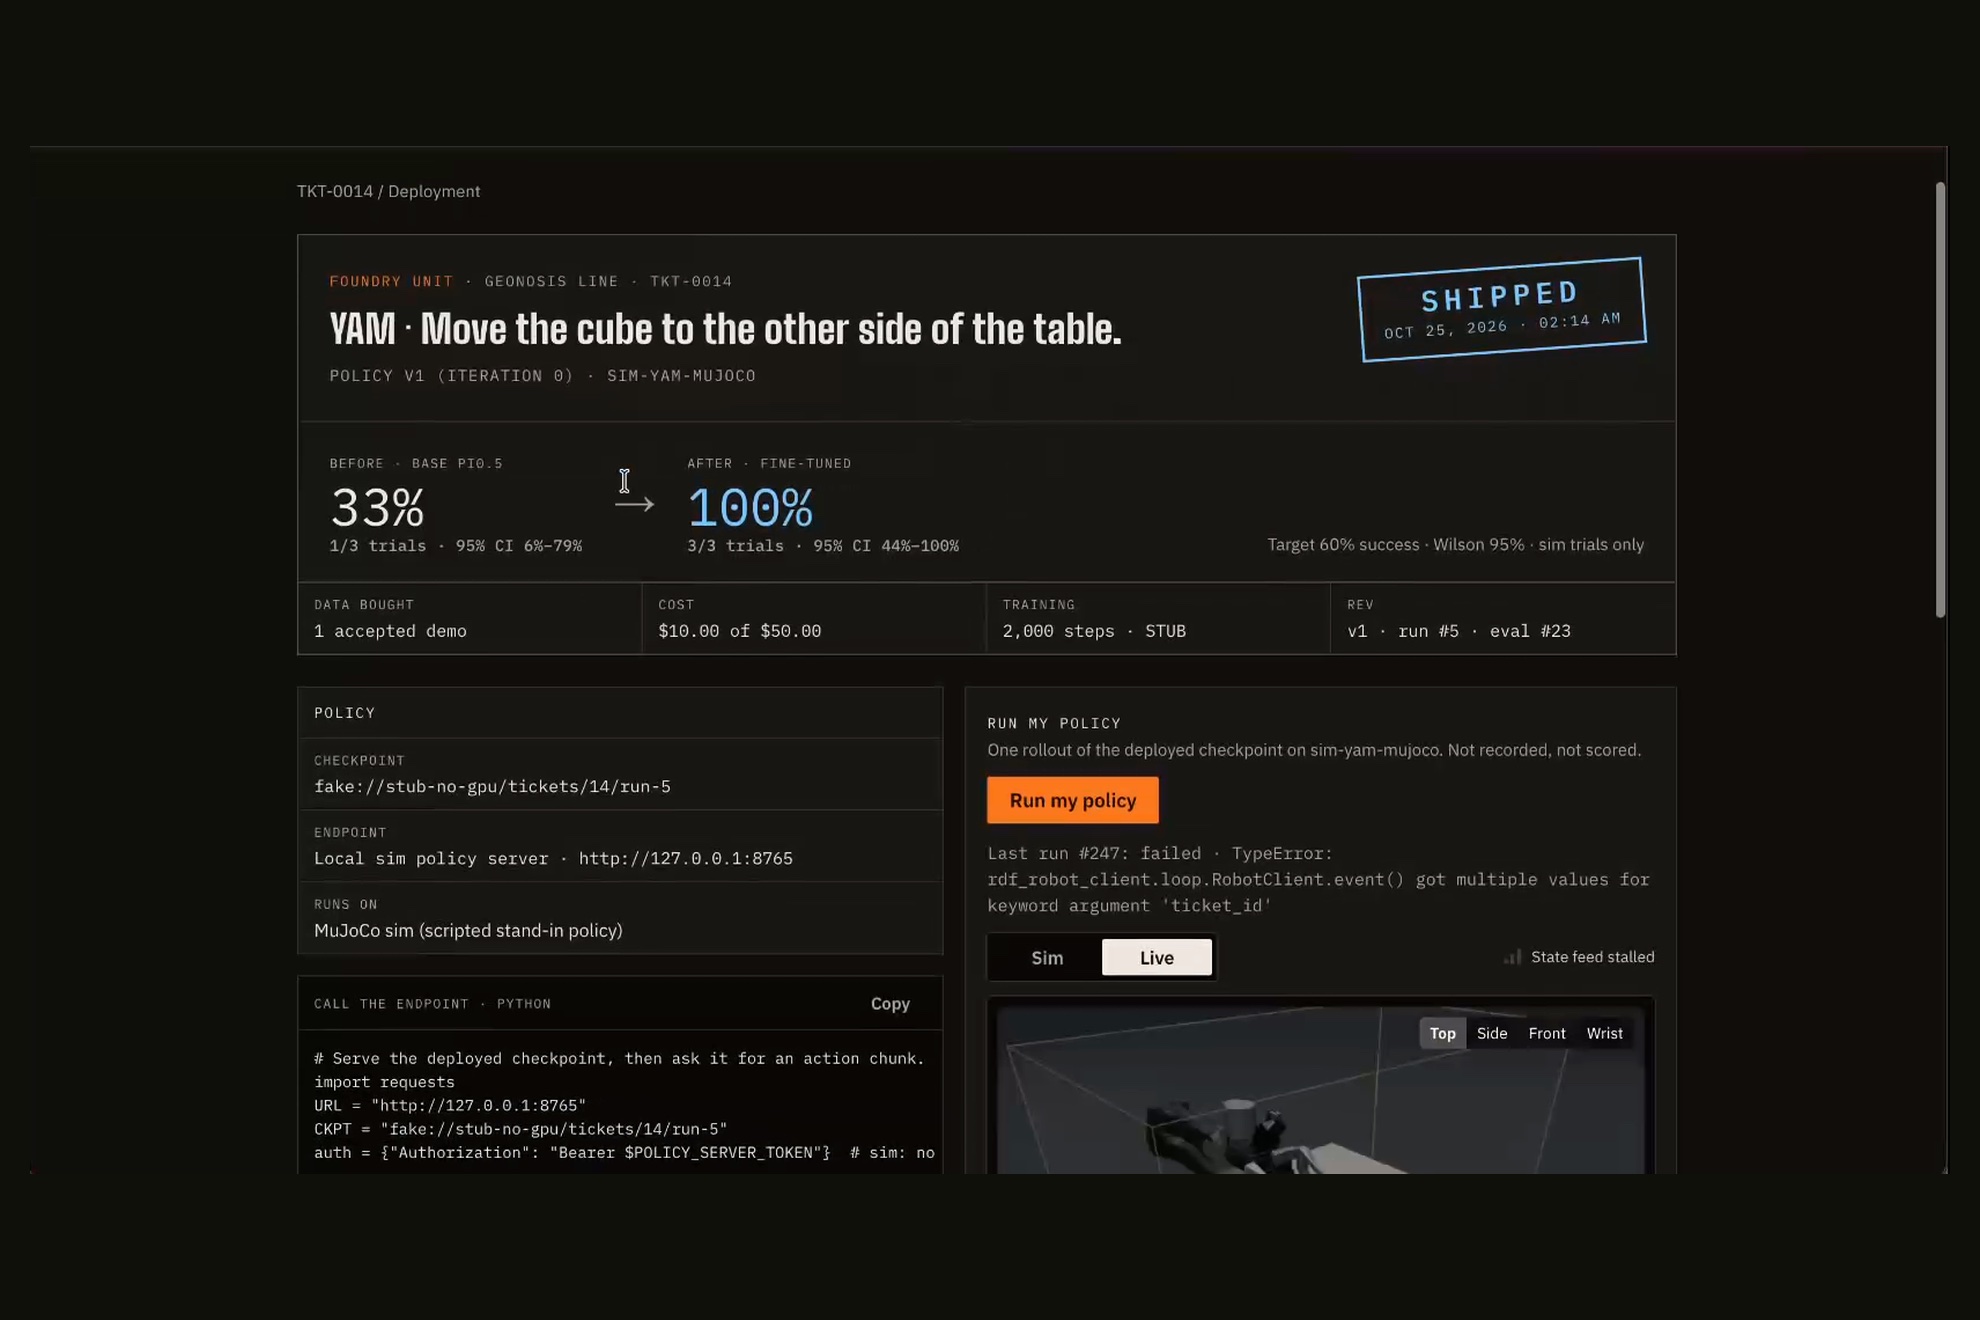
I care a lot about not mixing up the sim and the real thing, so everything simulated or stubbed says so wherever it shows up.
| Area | Status |
|---|---|
| SpacetimeDB, orchestrator, Claude diagnosis, planning and review | Real, on maincloud with real Claude calls |
| Factory Droids | Real Factory sessions, woken by SpacetimeDB writes |
| π0.5 LoRA fine-tune and policy server | Real, on a Modal H100 |
| Real YAM on the Jetson | Real: phone teleop, recording, guarded policy rollouts, Claude trial verdicts |
| MuJoCo YAM policy | Simulated. A scripted stand-in, not π0.5. Its before and after gap is a designed calibration, not learning |
| Payments | Stripe Connect test mode. No real money moves |
Hurdles
- No arm overnight. Nobody could be next to the YAM all night, so I built a physics sim of the same arm behind the same adapter and safety layer, and made sim or real a fact on every row.
- Droids that have to wait for hours. Agents normally run and finish. I needed them to park on a database condition and come back later with full context, so I built the wait-for protocol and resume bridge myself.
- Remote inference at control rate. A 157 ms round trip is several control steps. Async action chunks, dropping the stale prefix and crossfading made it smooth.
- A real arm is not a sim. Gravity pulls joints off their targets, the Jetson's ffmpeg has no H.264 encoder, and the arm has to fold back to rest safely after every trial. Each one cost hours.
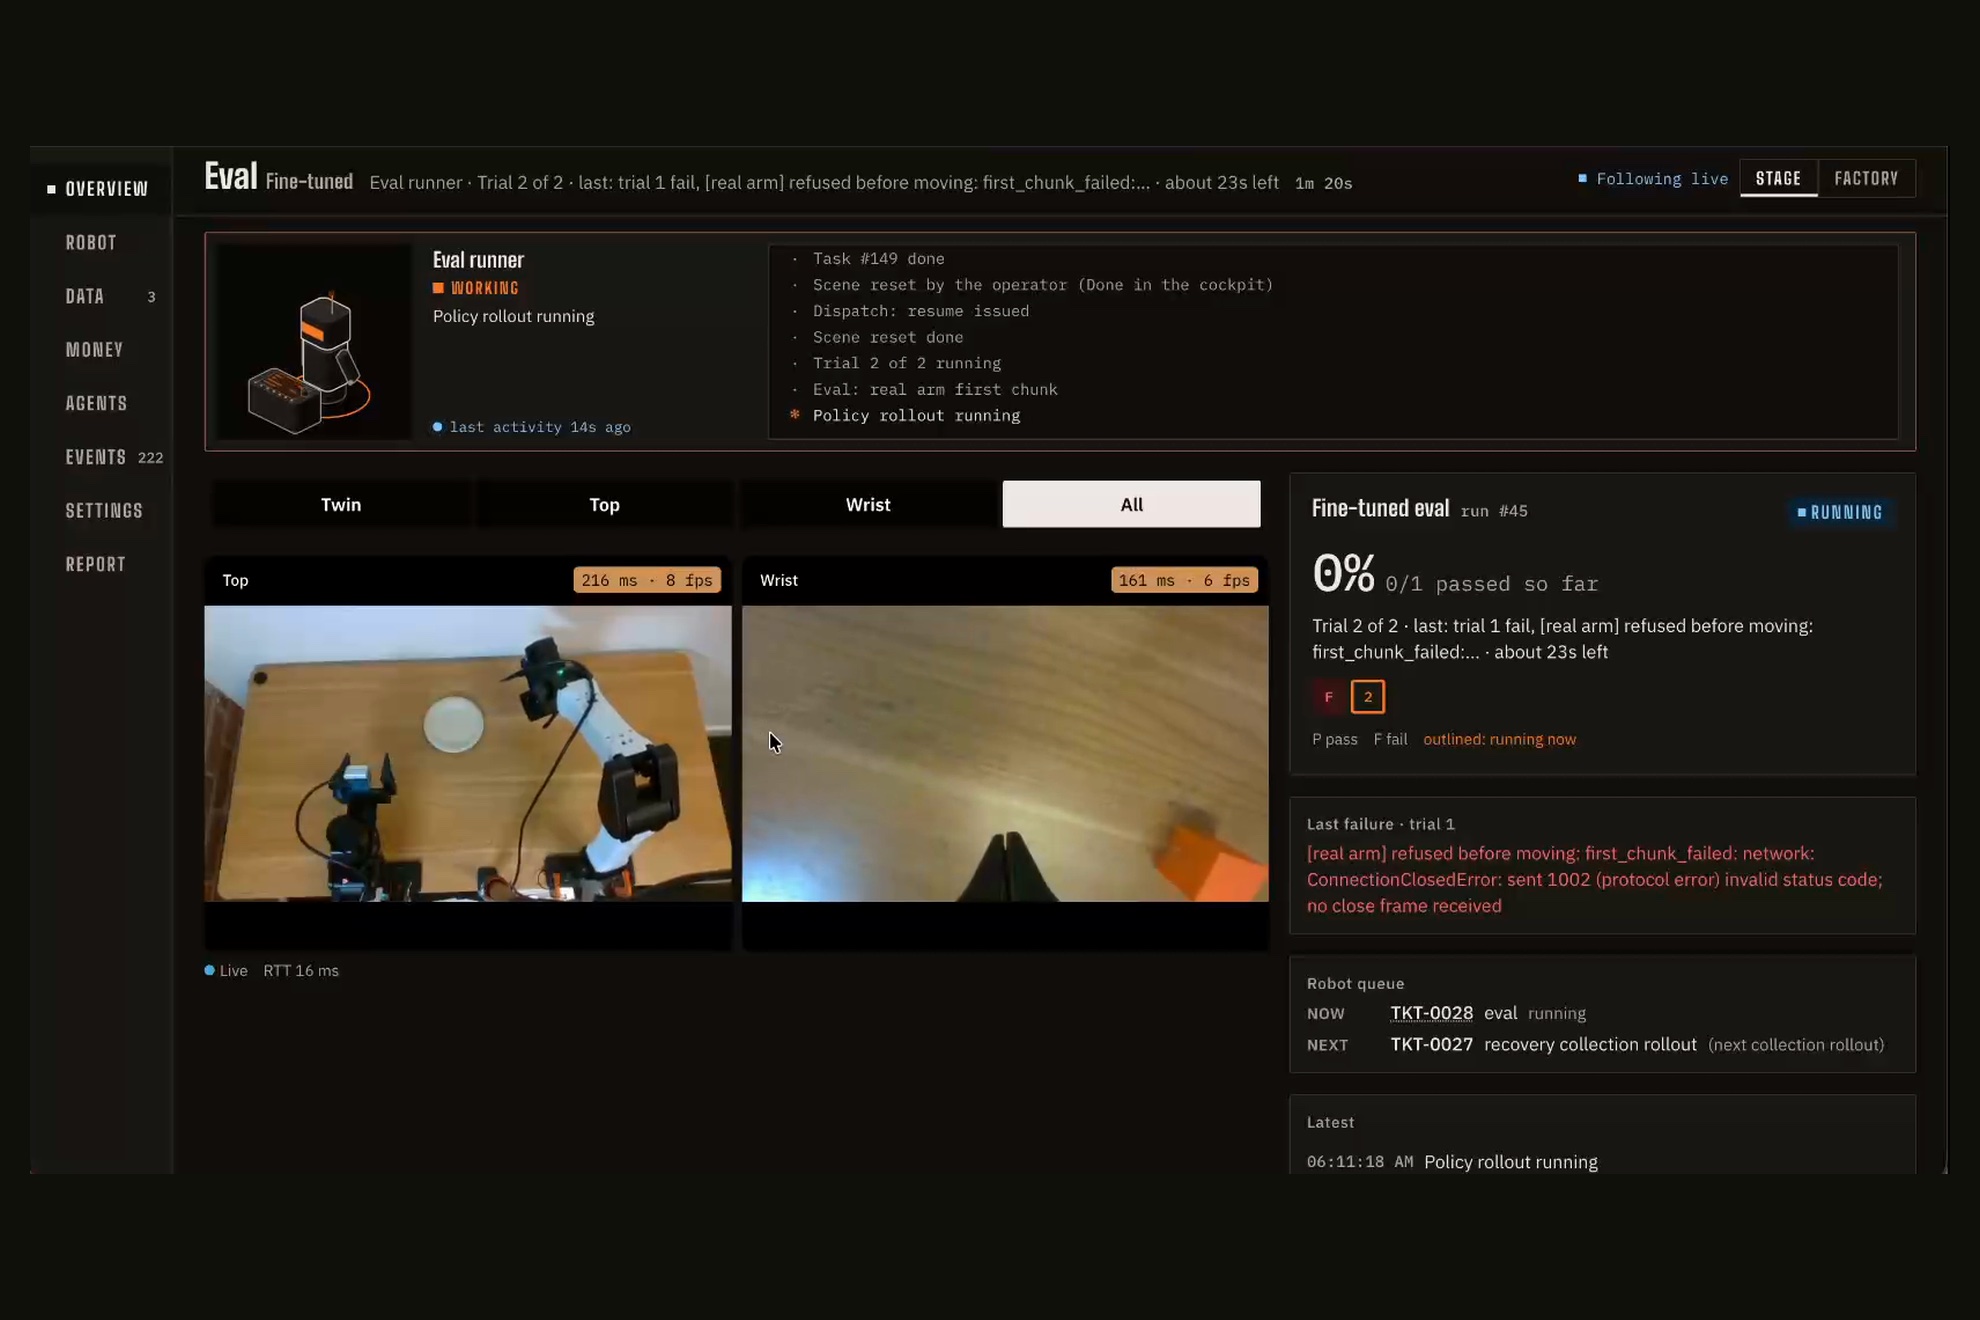
- Ten trials is a small sample. A strict confidence-interval rule can never certify 80% from 10 trials, so the factory ships on the point estimate and always shows the interval.
- Many agents, one repo. I built this with a team of coding agents working off one shared task board, and agents with stale git state reverted each other's work more than once. A pre-commit hook now refuses silent deletions.
What I learned
- The hard part of "AI deploys your robot" isn't the model. It's the plumbing that touches the physical world: who resets the cube, who takes over when it drops, how a GPU job wakes an agent, how a payout waits on a review.
- Agents need to be able to sleep. A session parked on a database condition costs nothing and comes back with full context. That turns a coding agent into a long-running worker.
- Guardrails belong in code, not prompts. The planner must cite a failure, a payout can't exceed the approved budget, the event log can't be rewritten.
- A sim is only useful if nobody can mistake it for the real thing.
What's next
- Run more real-arm tickets end to end and publish the before and after numbers.
- More data types for the planner: phone video, UMI-style handheld demos, autonomous rollouts.
- Open tickets automatically from failures in production, and rank contributors by accepted episodes.